Delivered either online or onsite, these instructor-led live GPU (Graphics Processing Unit) training courses use interactive discussions and hands-on exercises to demonstrate the core concepts of GPU technology and the methods required for programming them.
GPU training is offered as "online live training" or "onsite live training". Online live training, also known as "remote live training", is conducted through an interactive remote desktop session. Onsite live training can take place at your customer premises in Gaia or at NobleProg corporate training centers in Gaia.
NobleProg -- Your Local Training Provider
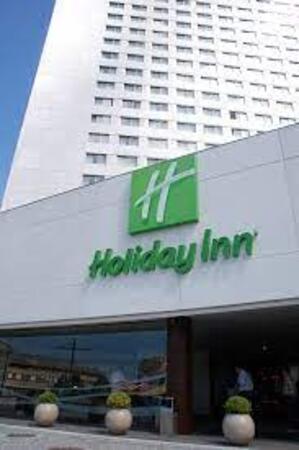
Holiday Inn Porto - Gaia
220, Rua Diogo Macedo, 220, Vila Nova de Gaia 4400-107 , Gaia, Portugal
From Porto by Metro
If you're coming from Porto city centre:
Take the Metro Line D (yellow line) toward Vila d’Este.
Get off at João de Deus.
From João de Deus, walk about 13 minutes to: Rua Diogo Macedo 220, 4400-107 Vila Nova de Gaia.
From Vila Nova de Gaia train station
If by “local train station” you mean Vila Nova de Gaia-Devesas:
The address is approximately 12 minutes walking from Vila Nova de Gaia station according to the accommodation's location information.
You can therefore walk directly rather than taking the metro.
This instructor-led programme on Gaia guides intermediate AI engineers in constructing and optimising neural network models using the Huawei Ascend platform and CANN toolkit. Learners will configure their environments, develop applications with MindSpore, and execute deployments to edge or cloud settings.
This live, instructor-led training on Gaia delves into Huawei's AI stack, covering the spectrum from the CANN SDK to the MindSpore framework. It supports both beginners and intermediate professionals in understanding how these elements integrate on Ascend hardware for lifecycle management and deployment.
This instructor-led, live training in Gaia (online or onsite) is aimed at beginner-level to intermediate-level developers who wish to use OpenACC to program heterogeneous devices and exploit their parallelism.
By the end of this training, participants will be able to:
Set up an OpenACC development environment.
Write and run a basic OpenACC program.
Annotate code with OpenACC directives and clauses.
This instructor-led session in Gaia focuses on deploying and optimizing CV and NLP models via the CANN SDK on Ascend hardware. Participants will gain the skills to convert models, integrate them into live pipelines, and boost inference performance for real-time detection and analysis.
This instructor-led, live training in Gaia (online or onsite) is designed for beginner to intermediate developers wishing to learn the essentials of GPU programming and the main frameworks and tools for developing GPU applications.
By the conclusion of this training, participants will be able to: Grasp the distinctions between CPU and GPU computing, as well as the advantages and challenges associated with GPU programming.
Select the most appropriate framework and tool for their specific GPU application.
Develop a fundamental GPU program that executes vector addition using one or more of the discussed frameworks and tools.
Utilise the relevant APIs, languages, and libraries to query device details, allocate and deallocate device memory, transfer data between host and device, launch kernels, and synchronise threads.
Leverage the corresponding memory spaces—such as global, local, constant, and private—to optimise data transfers and memory access patterns.
Apply the respective execution models, including work-items, work-groups, threads, blocks, and grids, to manage parallelism effectively.
Debug and test GPU programs using tools such as CodeXL, CUDA-GDB, CUDA-MEMCHECK, and NVIDIA Nsight.
Optimise GPU programs employing techniques like coalescing, caching, prefetching, and profiling.
This live, instructor-led training in Gaia provides advanced developers with the essential skills to construct, deploy, and optimize custom AI operators. Participants will gain mastery over the integration of CANN TIK and Apache TVM, enabling sophisticated optimization and scheduling on Huawei Ascend hardware to achieve real-world performance gains.
This instructor-led, live training in Gaia (online or onsite) is aimed at beginner-level to intermediate-level developers who wish to use different frameworks for GPU programming and compare their features, performance, and compatibility.
By the end of this training, participants will be able to:
Set up a development environment that includes OpenCL SDK, CUDA Toolkit, ROCm Platform, a device that supports OpenCL, CUDA, or ROCm, and Visual Studio Code.
Create a basic GPU program that performs vector addition using OpenCL, CUDA, and ROCm, and compare the syntax, structure, and execution of each framework.
Use the respective APIs to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Use the respective languages to write kernels that execute on the device and manipulate data.
Use the respective built-in functions, variables, and libraries to perform common tasks and operations.
Use the respective memory spaces, such as global, local, constant, and private, to optimize data transfers and memory accesses.
Use the respective execution models to control the threads, blocks, and grids that define the parallelism.
Debug and test GPU programs using tools such as CodeXL, CUDA-GDB, CUDA-MEMCHECK, and NVIDIA Nsight.
Optimize GPU programs using techniques such as coalescing, caching, prefetching, and profiling.
This instructor-led training in Gaia provides an introduction to CloudMatrix for scalable AI inference. Participants will learn to deploy, optimize, and monitor models leveraging CANN and MindSpore. Hands-on exercises address packaging, conversion, serving, and performance tuning for both real-time and batch workloads.
This instructor-led live course in Gaia explores the fundamental principles and practical skills required to deploy AI models on Ascend edge devices using the CANN toolkit, enabling participants to master compilation, optimization, and management within constrained environments.
This instructor-led live training in Gaia (online or onsite) is designed for beginner to intermediate developers who wish to install and use ROCm on Windows to program AMD GPUs and exploit their parallelism.
By the end of this training, participants will be able to:
Set up a development environment that includes ROCm Platform, an AMD GPU, and Visual Studio Code on Windows.
Create a basic ROCm program that performs vector addition on the GPU and retrieves the results from the GPU memory.
Use ROCm API to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Use HIP language to write kernels that execute on the GPU and manipulate data.
Use HIP built-in functions, variables, and libraries to perform common tasks and operations.
Use ROCm and HIP memory spaces, such as global, shared, constant, and local, to optimize data transfers and memory accesses.
Use ROCm and HIP execution models to control the threads, blocks, and grids that define the parallelism.
Debug and test ROCm and HIP programs using tools such as ROCm Debugger and ROCm Profiler.
Optimize ROCm and HIP programs using techniques such as coalescing, caching, prefetching, and profiling.
This instructor-led, live training in Gaia (online or onsite) is aimed at beginner-level to intermediate-level developers who wish to use ROCm and HIP to program AMD GPUs and exploit their parallelism.
By the end of this training, participants will be able to:
Set up a development environment that includes ROCm Platform, a AMD GPU, and Visual Studio Code.
Create a basic ROCm program that performs vector addition on the GPU and retrieves the results from the GPU memory.
Use ROCm API to query device information, allocate and deallocate device memory, copy data between host and device, launch kernels, and synchronize threads.
Use HIP language to write kernels that execute on the GPU and manipulate data.
Use HIP built-in functions, variables, and libraries to perform common tasks and operations.
Use ROCm and HIP memory spaces, such as global, shared, constant, and local, to optimize data transfers and memory accesses.
Use ROCm and HIP execution models to control the threads, blocks, and grids that define the parallelism.
Debug and test ROCm and HIP programs using tools such as ROCm Debugger and ROCm Profiler.
Optimize ROCm and HIP programs using techniques such as coalescing, caching, prefetching, and profiling.
This live training in Gaia introduces the CANN toolkit for AI framework developers. Participants will learn to configure environments, convert models, and deploy applications on Ascend hardware using MindSpore, TensorFlow, or PyTorch, covering the complete workflow from training to inference.
Master the optimization of AI workloads on Ascend, Biren, and Cambricon through this practical training in Gaia. You will learn to benchmark models, uncover performance bottlenecks, and apply graph, kernel, and operator-level optimizations. Additionally, you will tune deployment pipelines to boost throughput and minimize latency across these leading platforms.
Elevate neural network inference performance on Ascend AI processors through this advanced, instructor-led training in Gaia. Delve into the CANN runtime architecture, utilising the Graph Engine, TIK, and TVM for profiling, custom operator creation, and resolving memory bottlenecks.
Migrate CUDA applications to Chinese GPU architectures such as Huawei Ascend and Biren in Gaia. This instructor-led course guides advanced programmers through code translation and performance optimization, featuring hands-on labs for porting CUDA codebases to new SDKs.
This instructor-led live training, delivered in Gaia (either online or onsite), is tailored for developers from beginner to intermediate levels who wish to leverage CUDA for programming NVIDIA GPUs and utilizing their parallel capabilities.
Upon completion, participants will be able to:
Establish a development environment featuring the CUDA Toolkit, an NVIDIA GPU, and Visual Studio Code.
Create a fundamental CUDA program that executes vector addition on the GPU and retrieves the outcomes from GPU memory.
Employ the CUDA API to query device details, manage memory allocation and deallocation, transfer data between host and device, launch kernels, and synchronize threads.
Develop kernels that run on the GPU and manipulate data using CUDA C/C++.
Utilize CUDA built-in functions, variables, and libraries to carry out standard tasks and operations.
Apply CUDA memory spaces, including global, shared, constant, and local, to enhance data transfer and memory access efficiency.
Control threads, blocks, and grids via the CUDA execution model to define parallelism.
Debug and test CUDA programs using utilities such as CUDA-GDB, CUDA-MEMCHECK, and NVIDIA Nsight.
Enhance CUDA program performance using techniques like coalescing, caching, prefetching, and profiling.
This live training in Gaia provides intermediate AI developers with the skills to deploy models on Ascend processors using the CANN toolkit. The course covers converting frameworks such as PyTorch and TensorFlow, optimising performance, and troubleshooting issues to ensure efficient edge and cloud inference.
This live training on Gaia empowers developers to effectively programme and optimise applications on Biren AI accelerators. Attendees will delve into the GPU architecture, configure the SDK, and adapt CUDA code for Biren. The curriculum places a strong emphasis on performance tuning and debugging strategies.
This instructor-led live training in Gaia empowers developers with the necessary skills to construct and deploy AI models utilizing BANGPy and Neuware on Cambricon MLUs. Learners will configure their environments, develop optimized models, and integrate MLU acceleration into edge and data center applications.
This instructor-led live training in Gaia (online or onsite) is designed for beginner-level system administrators and IT professionals who wish to install, configure, manage, and troubleshoot CUDA environments.
By the end of this training, participants will be able to:
Comprehend the architecture, components, and capabilities of CUDA.
This live, instructor-led training in Gaia, available online or onsite, is designed for beginner to intermediate-level developers who want to utilize OpenCL for programming heterogeneous devices and leveraging their parallel capabilities.
By the end of this course, participants will be able to:
Set up a development environment that includes the OpenCL SDK, a supported OpenCL device, and Visual Studio Code.
Create a basic OpenCL program that performs vector addition on the device and retrieves results from device memory.
Use the OpenCL API to query device information and create contexts, command queues, buffers, kernels, and events.
Write kernels in OpenCL C that execute on the device and manipulate data.
Use OpenCL built-in functions, extensions, and libraries to perform common tasks and operations.
Optimize data transfers and memory accesses using OpenCL host and device memory models.
Control work-items, work-groups, and ND-ranges using the OpenCL execution model.
Debug and test OpenCL programs using tools such as CodeXL, Intel VTune, and NVIDIA Nsight.
Optimize OpenCL programs using techniques such as vectorization, loop unrolling, local memory, and profiling.
This instructor-led, live training in Gaia (online or onsite) is aimed at C++ developers who wish to use CUDA to accelerate applications, write high-performance GPU kernels, and leverage parallel algorithm libraries for scientific computing, data processing, and machine learning workloads.
This instructor-led, live training in Gaia (online or onsite) is aimed at C/C++ developers who wish to use CUDA to accelerate compute-intensive applications, including data processing, scientific simulations, machine learning workloads, and image processing pipelines.
This instructor-led, live training in Gaia (online or on-site) is aimed at software developers, data analysts, and technical professionals who wish to use TensorFlow 2.x and Keras to build, train, and deploy deep learning models for computer vision, natural language processing, and multimodal applications.
This instructor-led, live training course in Gaia explains how to program GPUs for parallel computing, utilize diverse platforms, navigate the CUDA platform and its capabilities, and execute various optimization techniques with CUDA. Key application areas include deep learning, analytics, image processing, and engineering solutions.
Read more...
Last Updated:
Testimonials (1)
Trainers energy and humor.
Tadeusz Kaluba - Nokia Solutions and Networks Sp. z o.o.
Course - NVIDIA GPU Programming - Extended
Provisional Upcoming Courses (Contact Us For More Information)
Online GPU training in Gaia, GPU (Graphics Processing Unit) training courses in Gaia, Weekend Graphics Processing Unit (GPU) courses in Gaia, Evening GPU training in Gaia, Graphics Processing Unit instructor-led in Gaia, GPU (Graphics Processing Unit) trainer in Gaia, Graphics Processing Unit (GPU) coaching in Gaia, Online Graphics Processing Unit (GPU) training in Gaia, Weekend GPU training in Gaia, Graphics Processing Unit (GPU) boot camp in Gaia, Graphics Processing Unit instructor-led in Gaia, GPU (Graphics Processing Unit) private courses in Gaia, Graphics Processing Unit (GPU) on-site in Gaia, GPU one on one training in Gaia, Graphics Processing Unit (GPU) instructor in Gaia, GPU (Graphics Processing Unit) classes in Gaia, Evening Graphics Processing Unit (GPU) courses in Gaia